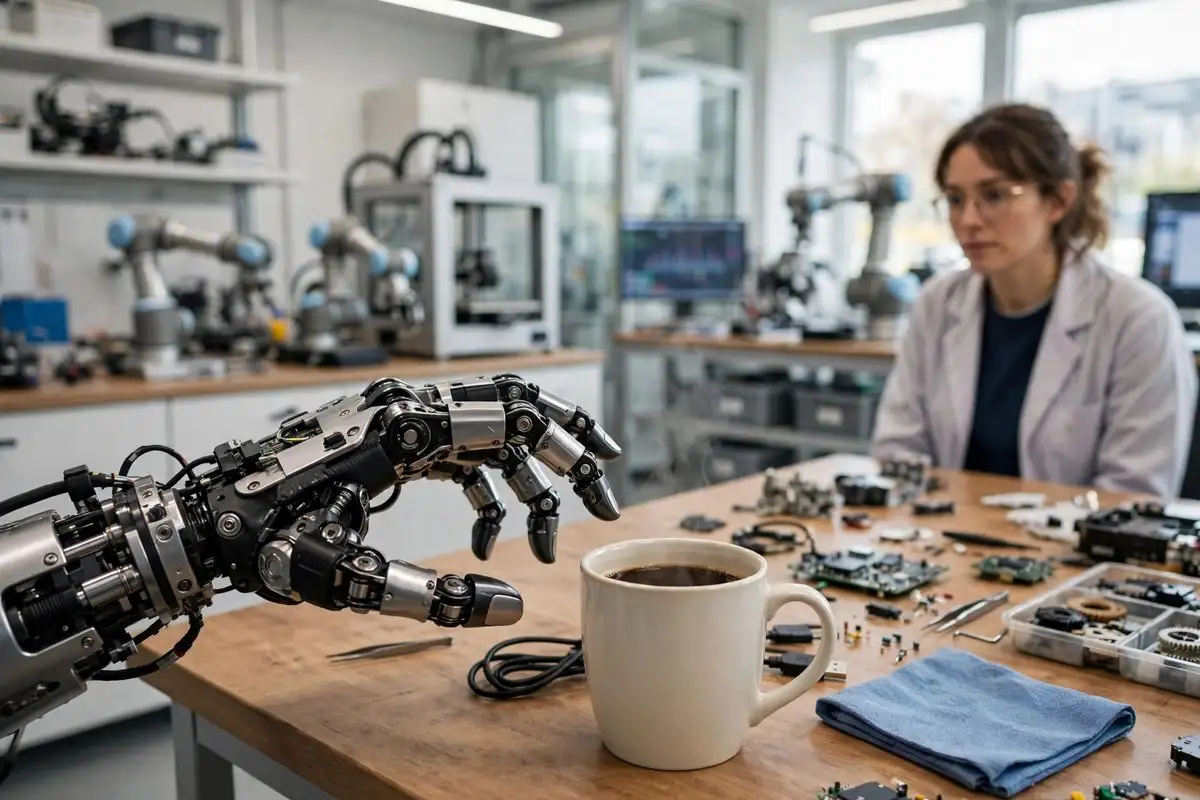
Nvidia has a new answer to the hardest problem in robotics: teaching a robot a job it has never done before. GR00T 2, introduced on November 9 at the Conference on Robot Learning in Austin, Texas, is a robot foundation model that learns from watching humans. Its headline number is striking. After five demonstrations of a task, the model averages 95 percent success across 50 dexterous tasks. But the whitepaper prints a condition next to that number, and the condition is the most interesting part of the announcement.
GR00T 2 is built on Nvidia’s Cosmos world models, and it works differently from a conventional robot controller. Instead of predicting only the next motor command, it jointly predicts how the scene will change and which actions the robot should take, generating a short chunk of future video and motor commands in a single diffusion transformer. The model takes recent video, a task instruction, and the robot’s current state as inputs, and it outputs both a prediction and a plan.
The numbers: 40, 71, 95
Nvidia’s tests use a set of 50 dexterous tasks, called Dexter-50, performed on a bimanual machine with two 22-degree-of-freedom Sharpa hands. None of the tasks appear in the target robot’s training data. The results, as Nvidia reports them:
| Demonstrations per task | Average success |
|---|---|
| Zero, no demonstration | 40 percent |
| One demonstration | 71 percent |
| Five demonstrations | 95 percent |
The zero-shot figure is the one that matters most for the long term. Forty percent on tasks the robot has never seen, with no demonstration at all, is the number that says the model is generalizing rather than memorizing. The five-demonstration figure is the one that matters most for the short term, because it describes the actual deployment pattern: show the robot a job a few times, fine-tune for about 30 minutes on a single RTX 5090 graphics card, and let it work.
A smaller variant, GR00T 2 Turbo, uses a 2-billion-parameter transformer and runs a prediction in 124 milliseconds on Nvidia’s Jetson Thor robot computer, which is fast enough for real-time control on the robot itself rather than in the cloud.
The asterisk the whitepaper prints itself
Here is the condition. The whitepaper says the 50 tasks were chosen among those the model learns with five episodes at a success rate of at least 80 percent. In plain terms, the tasks in the test were selected because the model could already learn them with five demonstrations. The 95 percent average is real, and it is high partly by construction. Nvidia does not say how large the pool was that the 50 tasks were drawn from, so nobody outside the company knows how selective the filter was.
That does not make the number false. It makes it a statement about a selected set, not a field reliability figure, and it is worth crediting Nvidia for disclosing the condition in the paper itself. The blog post’s headline figures omit it. The whitepaper does not. Anyone planning a deployment around the 95 percent number should read the paper first, because the gap between a lab benchmark and a factory floor is exactly where that selection effect lives.
400,000 hours of watching people work
The reason GR00T 2 can learn from a handful of demonstrations is the scale of what it watched first. The pretraining mix includes 402,730 hours of first-person human video, 10,184 hours of handheld-gripper demonstrations across 2,897 tasks, and 23,500 hours of robot teleoperation. The human video is the key ingredient: the model learns how hands move, how objects behave, and how tasks are sequenced, before it ever touches a robot.
Nvidia has opened 100,000 hours of that human data, the Human-1M-100K release, including video, language annotations, and head and hand motion data, under a CC BY 4.0 license that permits commercial and noncommercial use. That is a genuinely open contribution, and it is available now on Hugging Face.
The model also transfers skills across robot bodies, an approach Nvidia calls X-Adapt. One pretrained checkpoint covers parallel-gripper arms, dexterous hands, and the Unitree G1 humanoid. A skill learned from human video can, in principle, land on a different machine with a different hand. That is the promise that makes the 40 percent zero-shot figure worth watching: if the transfer holds up outside the lab, the cost of teaching each new robot drops sharply.
Open, but not yet downloadable
Nvidia calls GR00T 2 an open frontier world action model, and parts of the release are genuinely open. Isaac Lab 3.0, the robot training framework, is open source and generally available since October 20, with a Newton physics engine and up to 2.5 times the training throughput of the previous version. A developer preview of Isaac Lab-Arena 0.4 arrived at the conference, along with two new open benchmarks for industrial robot work, DexBench and VABAR.
For GR00T 2 itself, the situation is different. The research page says code will be available in December, and the announcement gives no download date, no license, and no link to model weights. Open, in this case, means the architecture, the demonstrations, and the published results are public now, and the code follows later. Teams that want to build on it should plan around December, not November.
Who is testing it, and what comes next
The early testers are industrial, not consumer. Nexuni is testing GR00T 2 for laundry handling, Foxconn is applying it to server-manufacturing automation, and Siemens is evaluating industrial uses. MicroAGI is working on Ethernet cable swapping. None of these is a production rollout. All of them are the kind of repetitive, dexterous work where five demonstrations and a short fine-tune could beat months of hand programming, if the transfer holds.
That is the right way to read this announcement. GR00T 2 is not a robot you can buy, and its best number comes with a condition its own authors printed. What it is, is the clearest sign yet that the robot industry is moving from imitation learning, where every task needs its own pile of robot demonstrations, to learning from human video, where the pile already exists. The 95 percent will get the headlines. The 40 percent, and the 400,000 hours behind it, are the numbers that will decide whether this works outside the lab.
The comparison that puts it in context is the open-weight race in language models, where small models keep beating rivals many times their size, and where the best AI agent still scores only 12 percent on the hardest new benchmark. Robotics is earlier in that curve, and further from the factory floor. GR00T 2 is a step along it, with its limits printed in its own paper, which is exactly how a step like this should be announced.